


Workload Assessment
We define the models you want to run, concurrent users, and 256K or extended context requirements. Throughput and latency targets are assessed alongside your existing infrastructure.
Built for Frontier-Scale Private AI
Overview
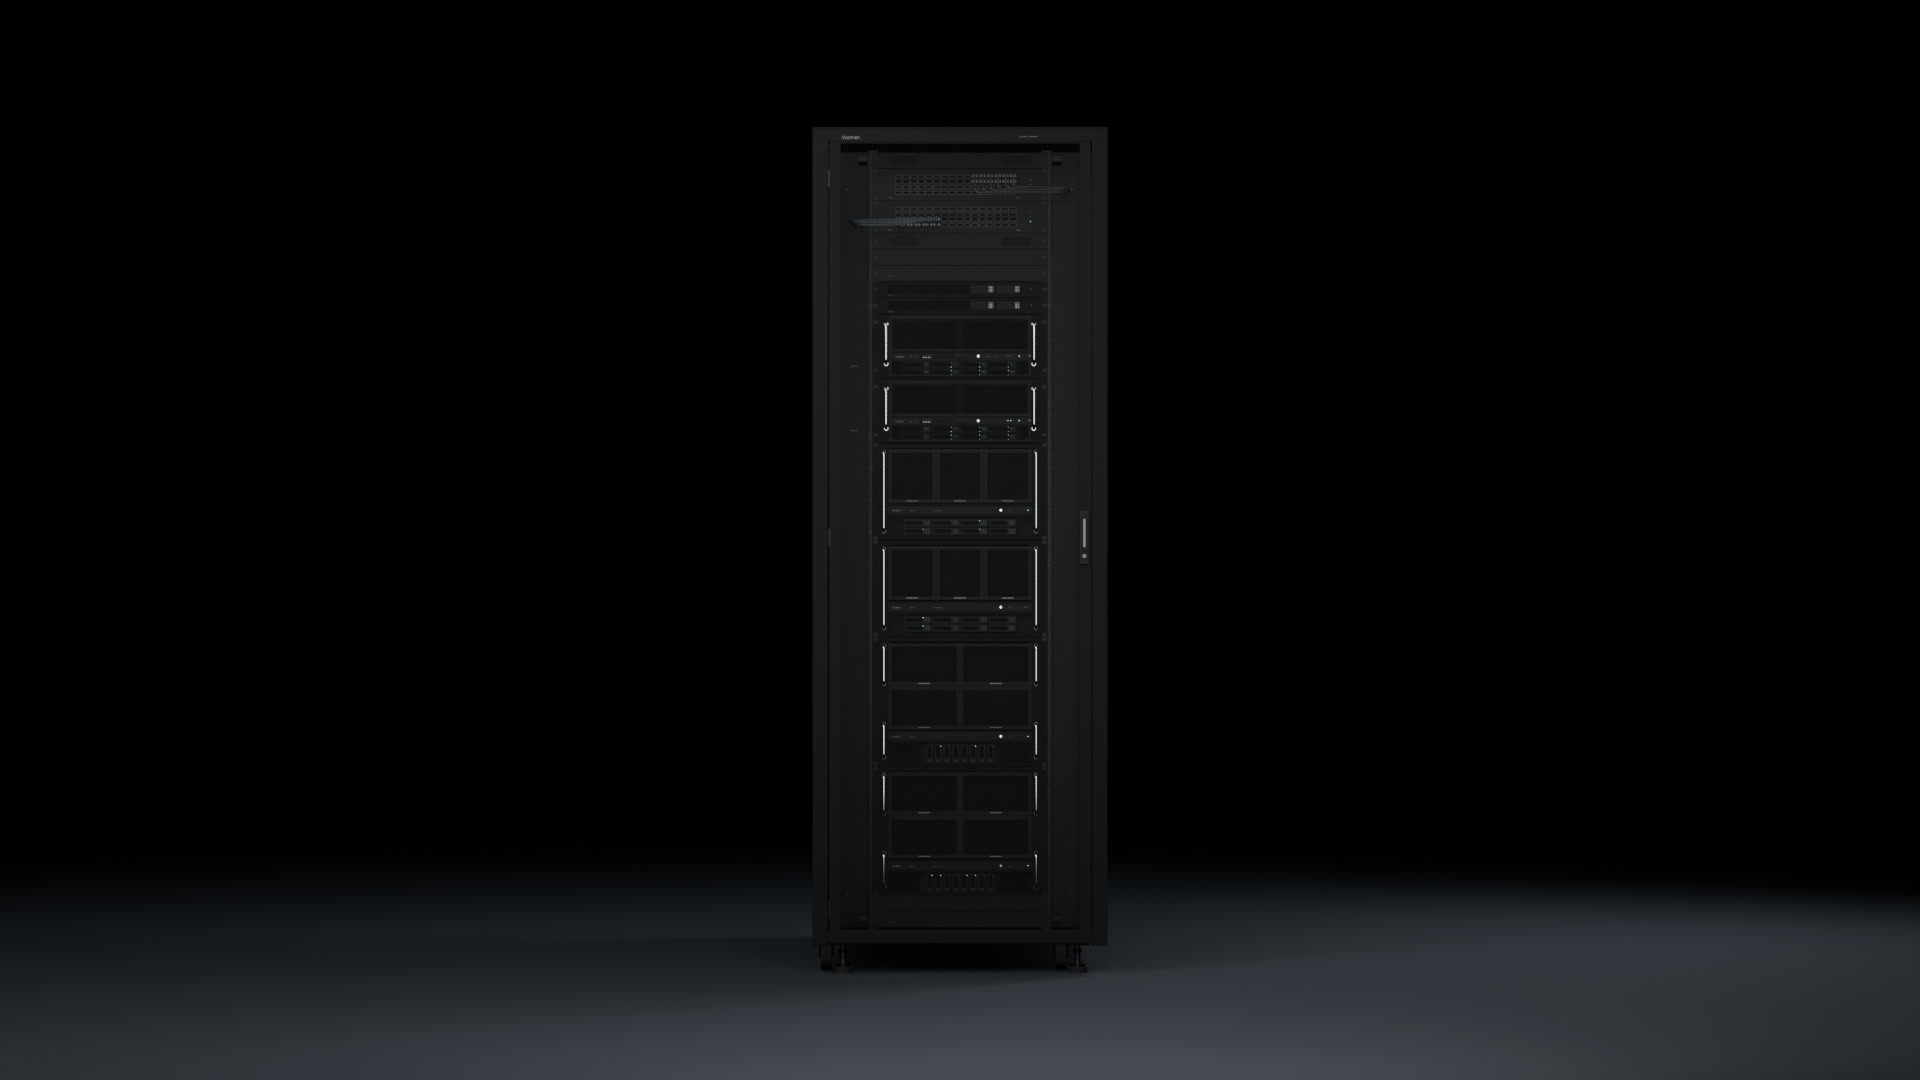
Vostner Cluster is a custom multi-rack private AI platform built for frontier models, high concurrency, large context windows, and enterprise-scale workloads. Compute, storage, and networking are configured around the models you need to run, with hardware validated for each deployment. Expand capacity independently as demand grows, while keeping your AI infrastructure under your control.
Every Cluster is designed to order around your workloads, your organization, and your existing infrastructure.
We define the models you want to run, concurrent users, and 256K or extended context requirements. Throughput and latency targets are assessed alongside your existing infrastructure.
Your requirements shape GPU and accelerator memory sizing, compute nodes, storage, and high-speed networking. Redundancy and rack layout are designed around your deployment.
We verify model compatibility and test inference under full load, including concurrent users, thermal behavior, and power. Failover and redundancy checks are included where applicable.
From rack installation and Vostner Node/Console setup to model deployment, we bring your Cluster into operation with monitoring, updates, and ongoing support.
Manage models, nodes, capacity, and cluster health from one control plane.
Tell us what you want to run. We’ll design the infrastructure around it.
Contact Us