
Vostner Compact
Private AI, sized for your workspace.
Starting at $4,999
32 GB VRAM · 128 GB ECC · 2 TB NVMe
A short-depth rack option.
Prefer a rack-mounted setup? Explore Vostner Compact in a short-depth enclosure, configured around your workspace and workloads.
Discuss your configuration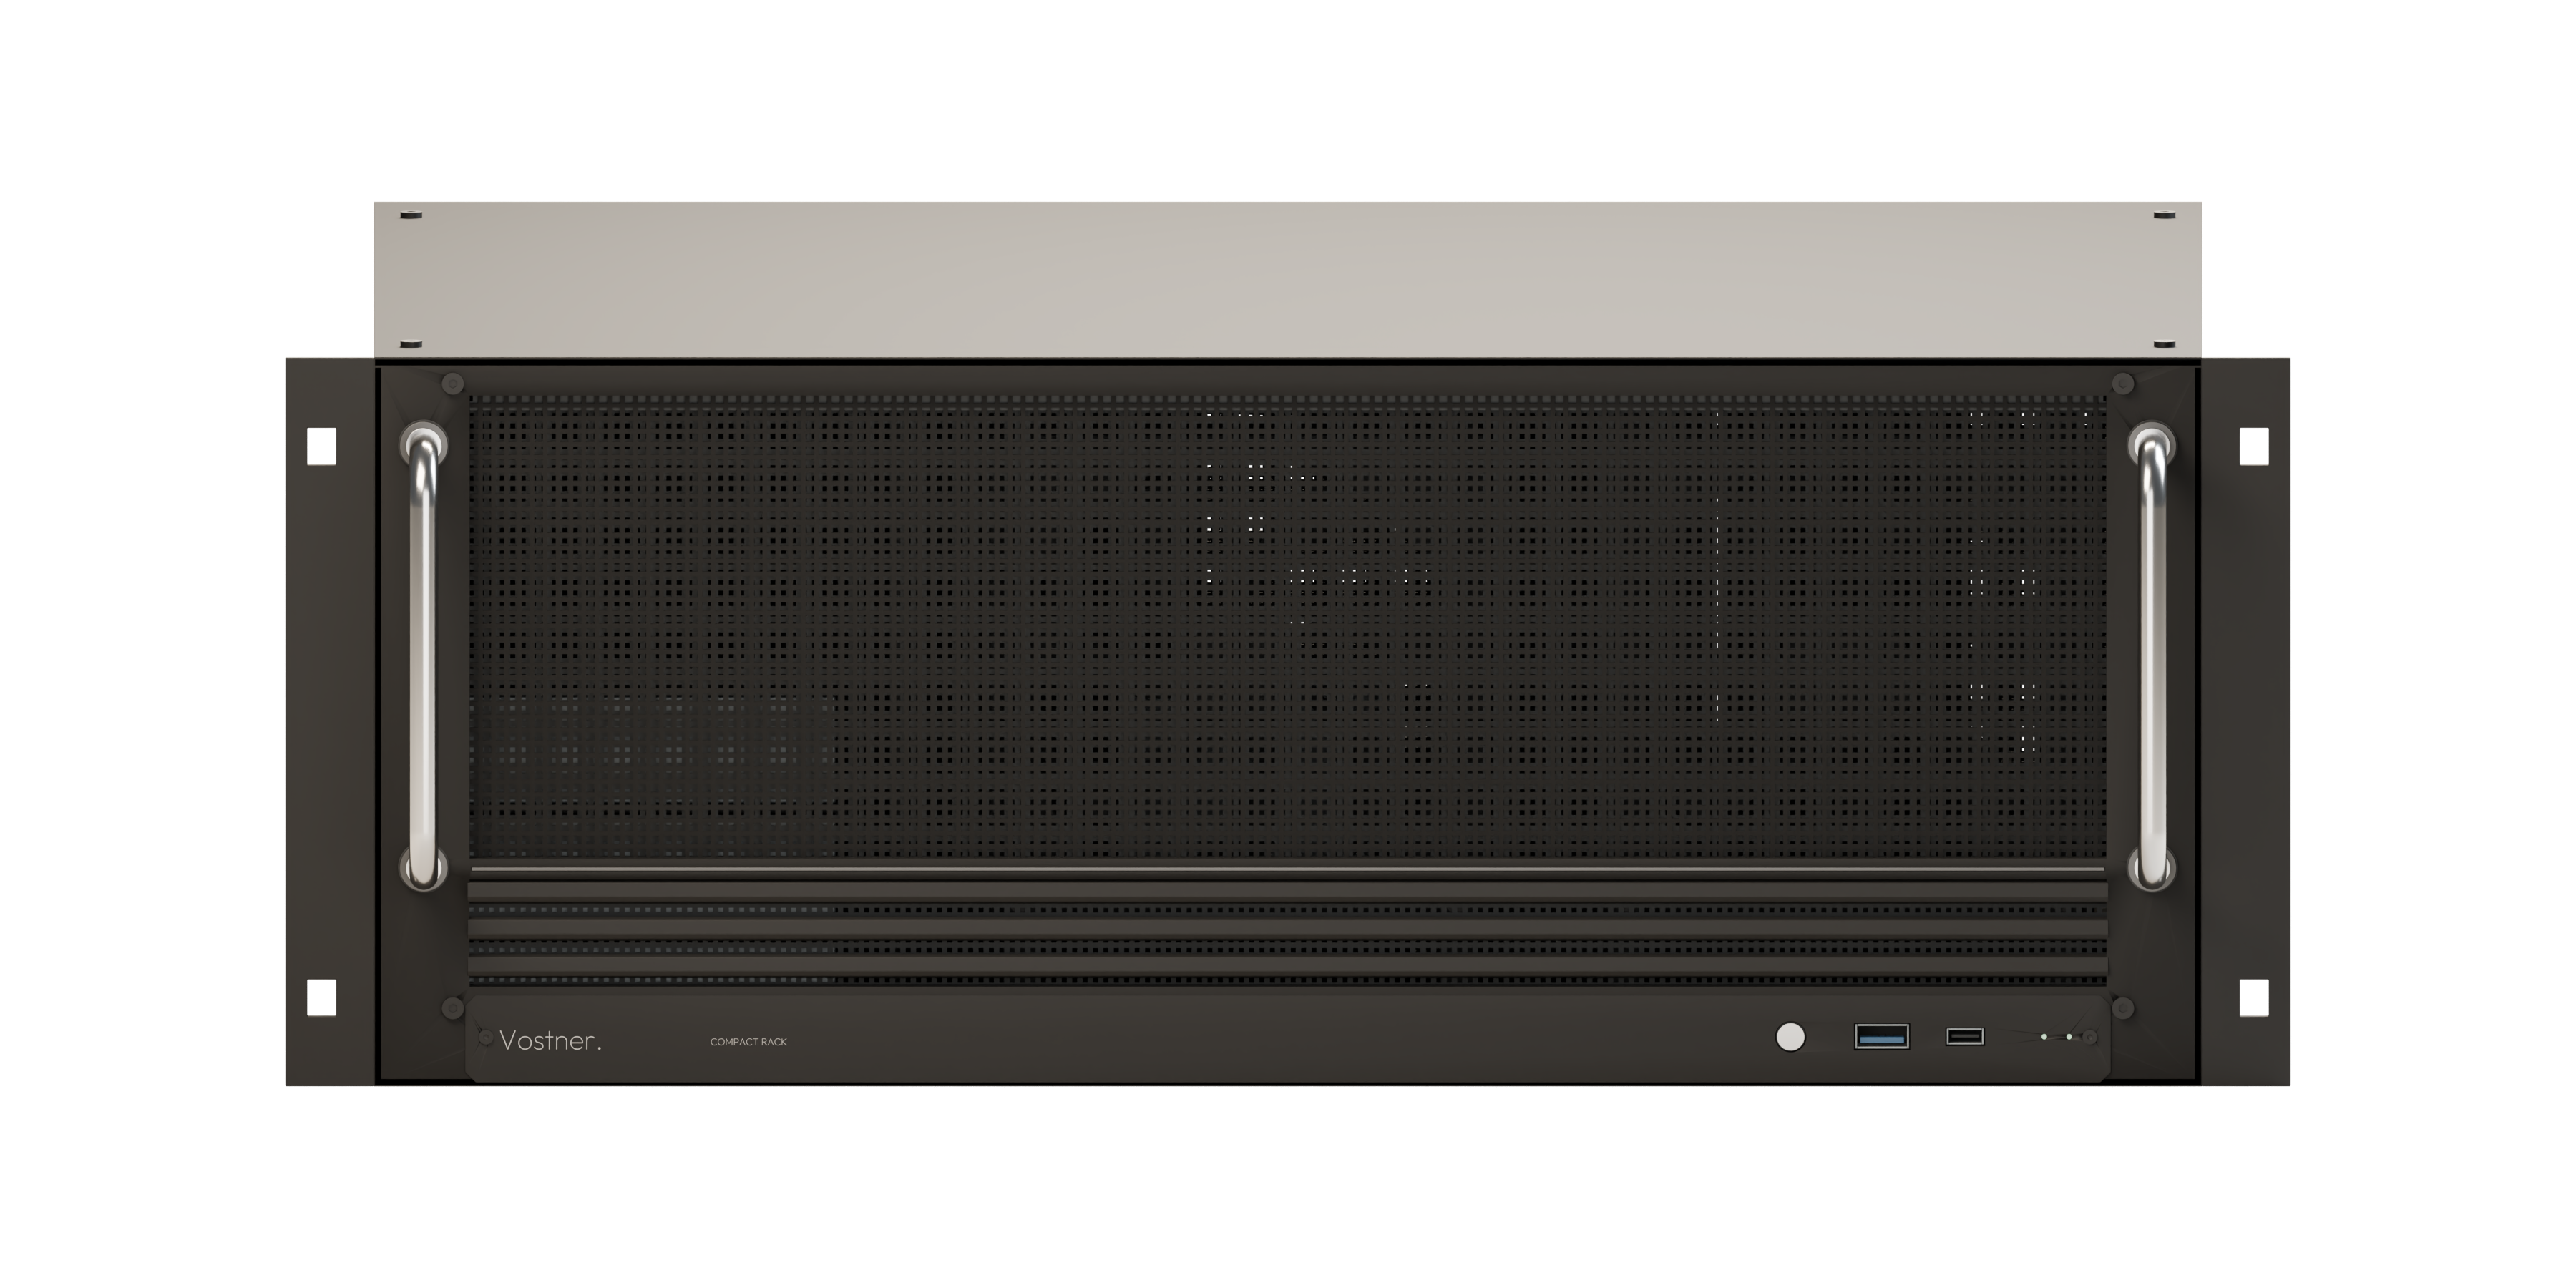
Vostner Compact brings dedicated local AI into a workspace-sized system built for individuals and small teams.
Run private assistants, RAG, coding tools, agents, and internal workloads without dedicated datacenter infrastructure.
Dedicated AI Compute
Local inference on your own hardware.
Compact Footprint
Serious AI infrastructure without dedicated server-room space.
Purpose-Built Local AI
Designed around private assistants, RAG, agents, and internal workloads.
Built for Responsive Local AI
Qwen 3.8 27B · Published FP8 checkpoint
*Base Vostner Compact with 32 GB accelerator memory. Higher-capacity configurations are available.
Estimate assumptions & sources
Published peak memory bandwidth ÷ 30.9 GB checkpoint size. This simplified model assumes one full checkpoint-sized memory read per output token, one user, full accelerator residency and 100% bandwidth utilization. Checkpoint size is a proxy for weight traffic, not a measured per-token read. It excludes compute, KV cache, runtime overhead, batching and speculative decoding. These values are not measured TPS, guaranteed performance or validated hardware rankings.
Built for Small Teams
Compact gives smaller teams dedicated private AI without requiring rack-scale infrastructure or a dedicated AI operations team.
Explore for Teams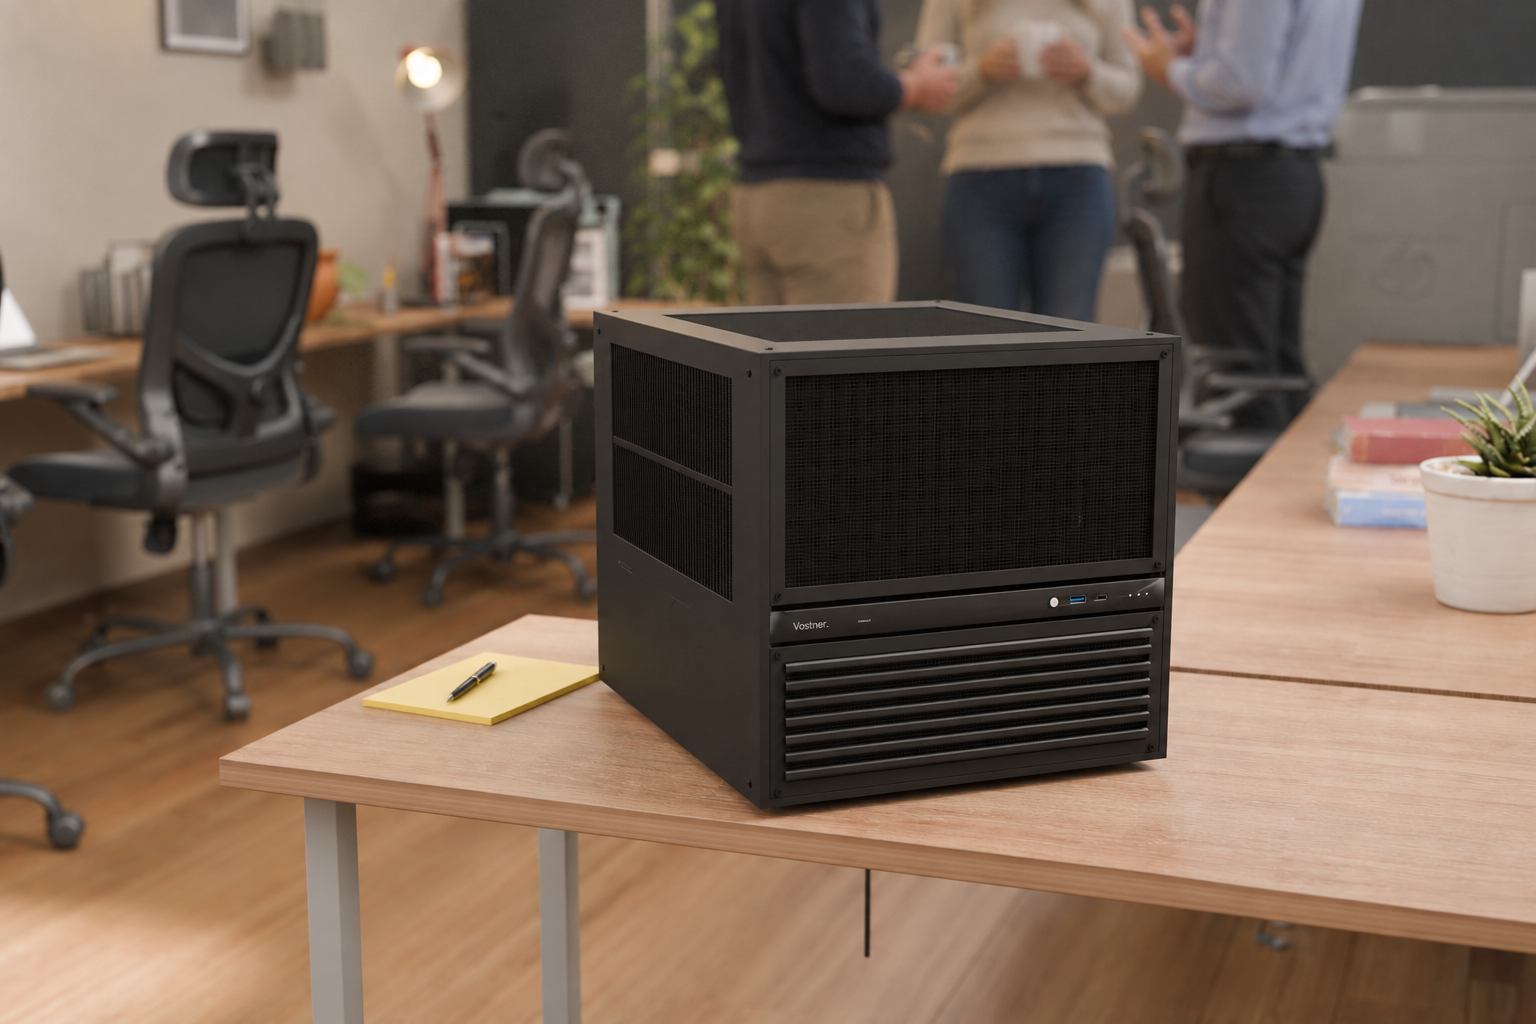
Works with Vostner Console
Manage models, capacity, and system health from one control plane.
Model management
Deploy and manage your local models.
Live capacity
See the resources available to your workloads.
System health
Keep hardware and services in view.
Ready to Talk?
Tell us what you want to run. We’ll design the infrastructure around it.
Contact Us